Data and MLOpen source
orya-benchmark-pack
A focused analysis reference built for analysts, data scientists, and ML engineers who need fast, credible baselines, cleaner comparisons, and structured outputs from tabular datasets.
The brief
Before deeper modelling on a tabular dataset, analysts, data scientists, and ML engineers need an honest baseline: what a simple model achieves and which features actually matter. Without one, exploratory work tends to stay vague and later comparisons are hard to trust.
orya-benchmark-pack had to produce credible baselines quickly from inside a notebook, read common dataset formats, frame the task automatically, validate results properly, and leave structured artifacts that can be reviewed and reused once the heavier modelling work begins.
How we approached it
- 1
From file to framed task
CSV and Parquet datasets load directly in a notebook, and the tool frames the task automatically so a benchmark can start without manual setup.
- 2
Validation built into baselines
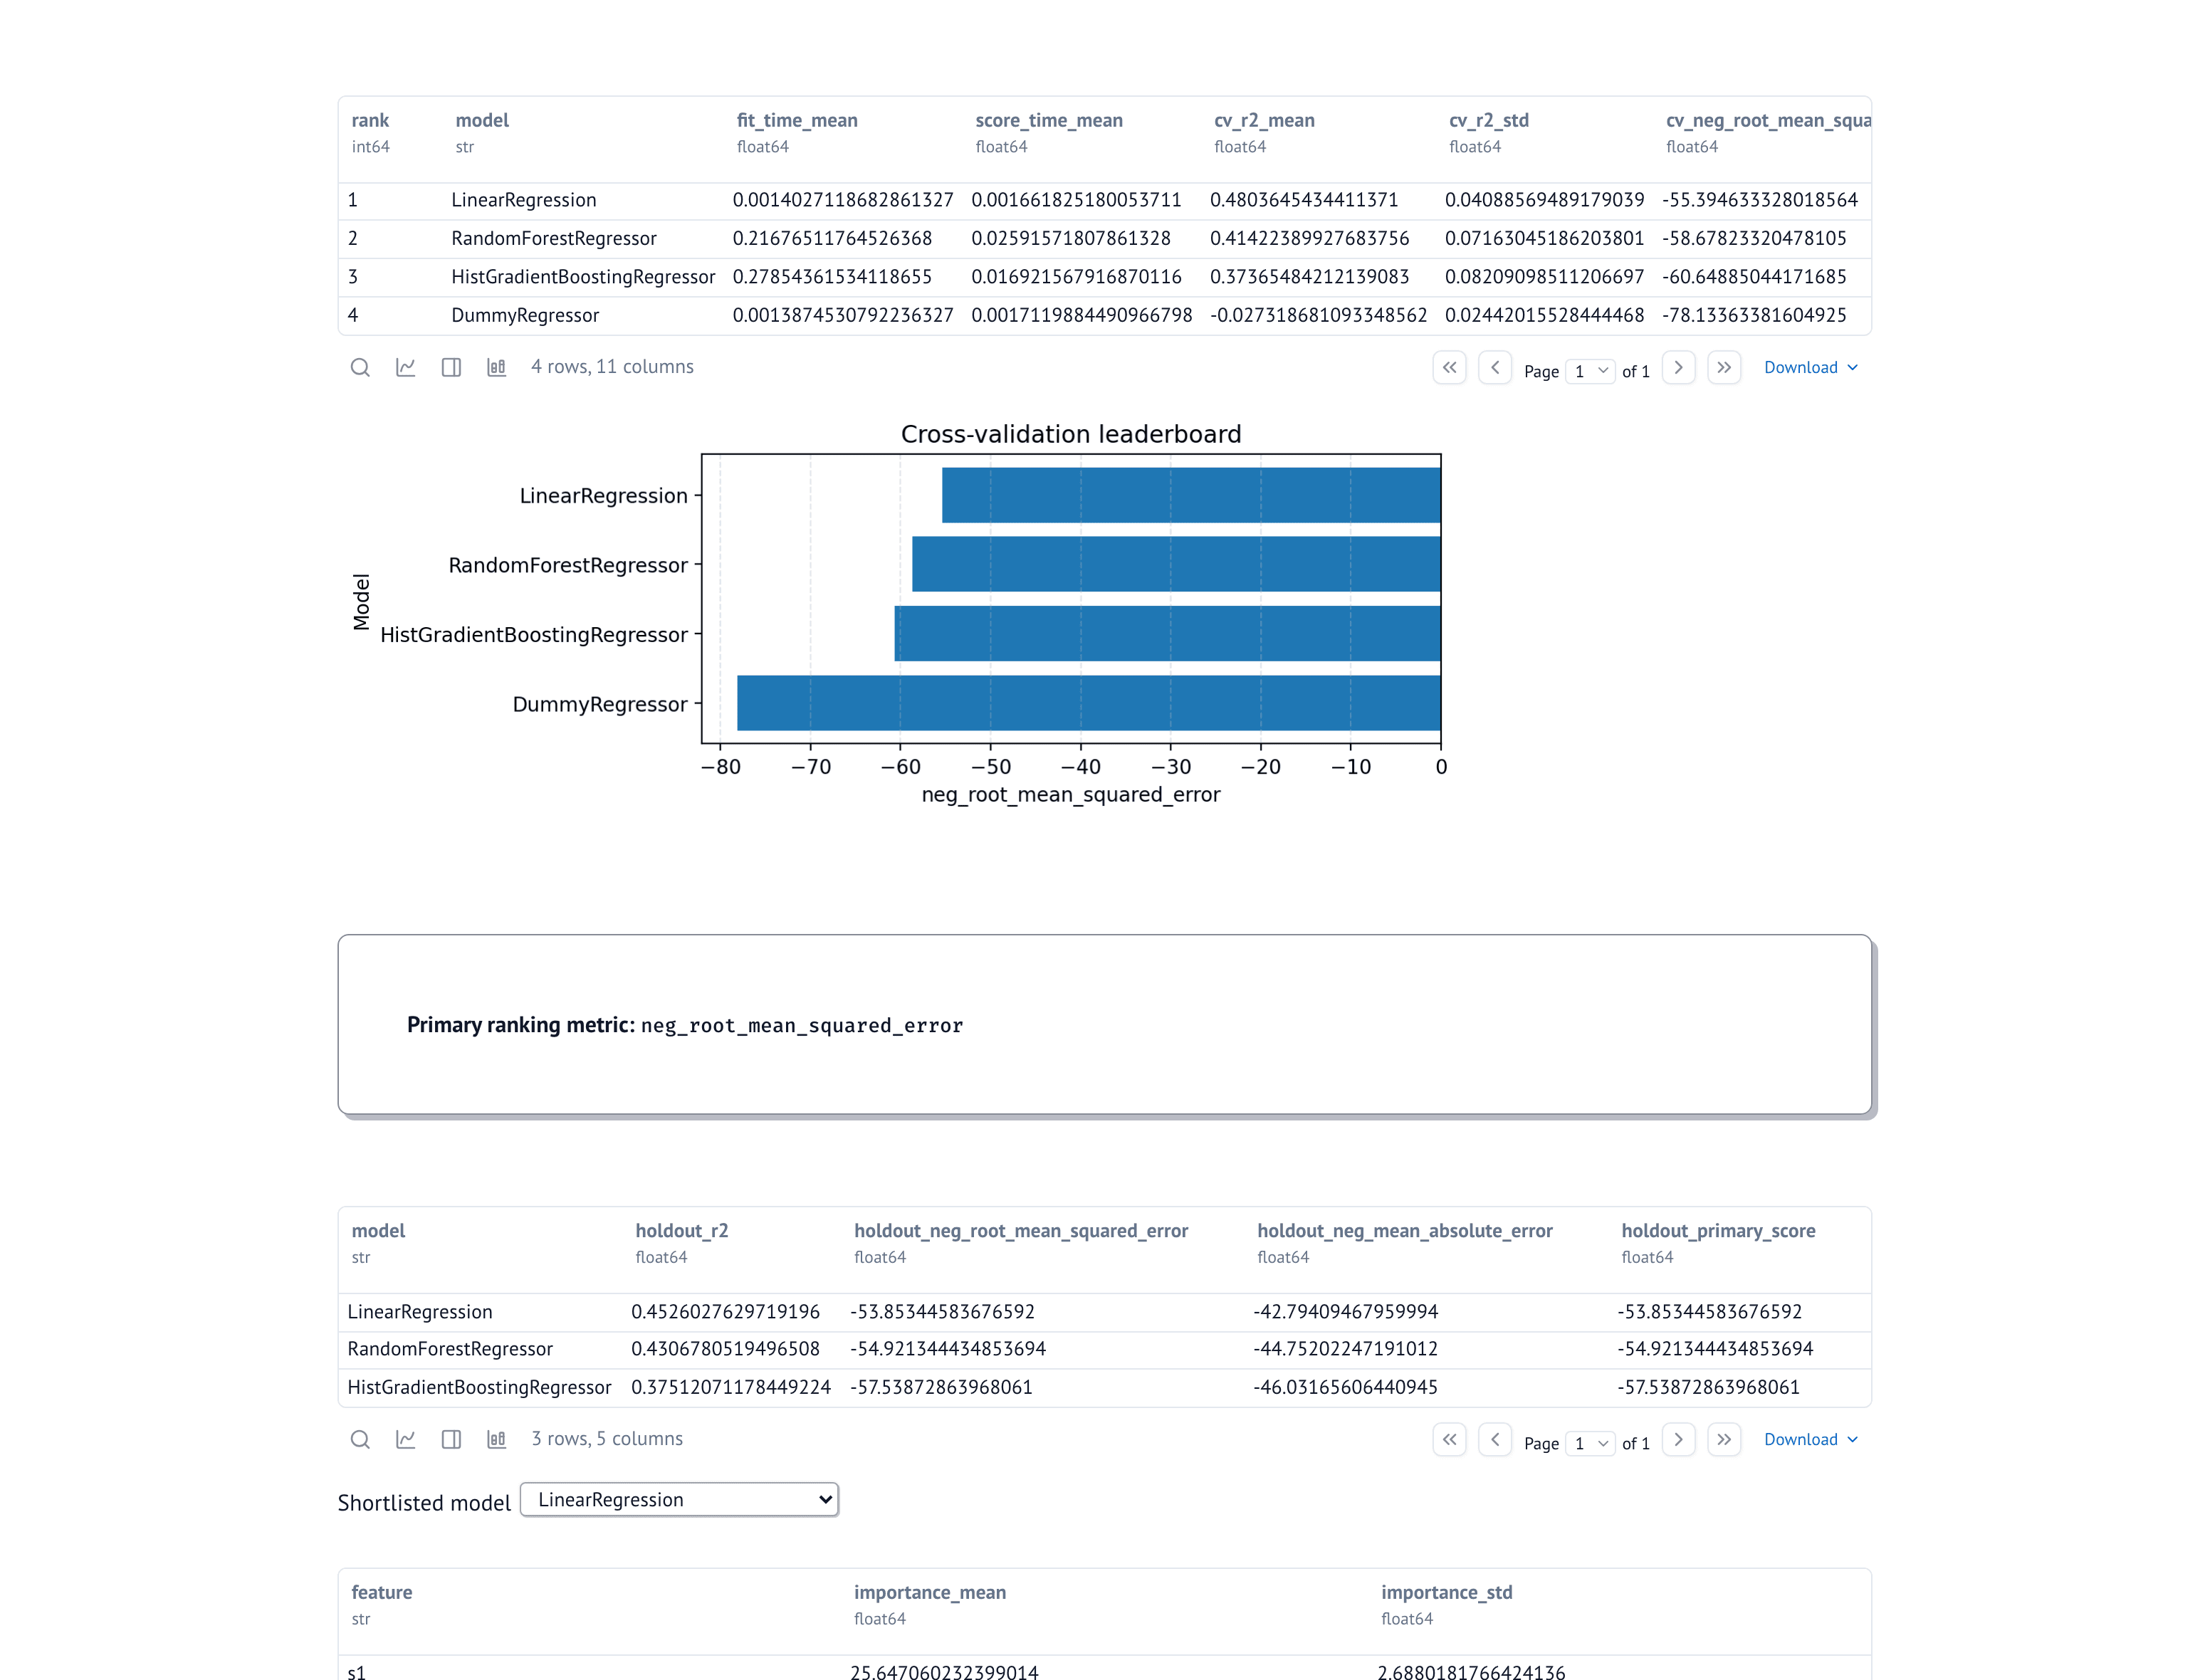
Baselines are scored with cross-validation and holdout checks, so the first numbers on a dataset are ones that can be compared with confidence.
- 3
Outputs worth keeping
Permutation feature importance and clean artifact export leave a reviewable record of what the baseline found, ready to reuse in later analysis.
What we delivered
- CSV and Parquet dataset handling with automatic task framing
- Baseline benchmarking with cross-validation and holdout checks
- Permutation feature importance and clean artifact export for later review
What it had to achieve
- Support faster baseline understanding before heavier modelling
- Reduce vague exploratory work by adding a clearer benchmark layer
- Create repeatable analysis outputs that can be reviewed and reused